Whole-body humanoid object transportation in cluttered environments
Anonymous Authors
Abstract.
Object transportation is a fundamental capability for humanoid robots operating in real-world, human-centric environments, yet existing methods struggle when clutter constrains free space around both the robot and its carried payload.
We present Hotice, a whole-body humanoid learning framework for transporting objects through such cluttered environments.
First, we introduce Humanoid-Object Decoupled Potential Fields, which jointly encode collision-avoidance guidance for the robot and the carried object, enabling coordinated, obstacle-aware motion for both.
Second, to address the large action space inherent to whole-body loco-manipulation, we design a dual-agent reinforcement learning architecture that decouples upper- and lower-body control while preserving whole-body coordination via shared state observations and rewards.
To train a policy that generalizes across diverse cluttered scenes, we further employ a specialist-to-generalist distillation strategy, in which privileged teacher policies are distilled into a single deployable student policy.
We evaluate Hotice in MuJoCo simulation and on a real Unitree G1 humanoid, demonstrating effective and robust object transportation across cluttered scenarios for objects of varying shapes.
Our results show that Hotice reliably coordinates whole-body motion and object-aware collision avoidance, generalizing effectively to previously unseen cluttered environments while achieving strong performance in sim2real deployment.
Method.
Hotice is composed of three main components.
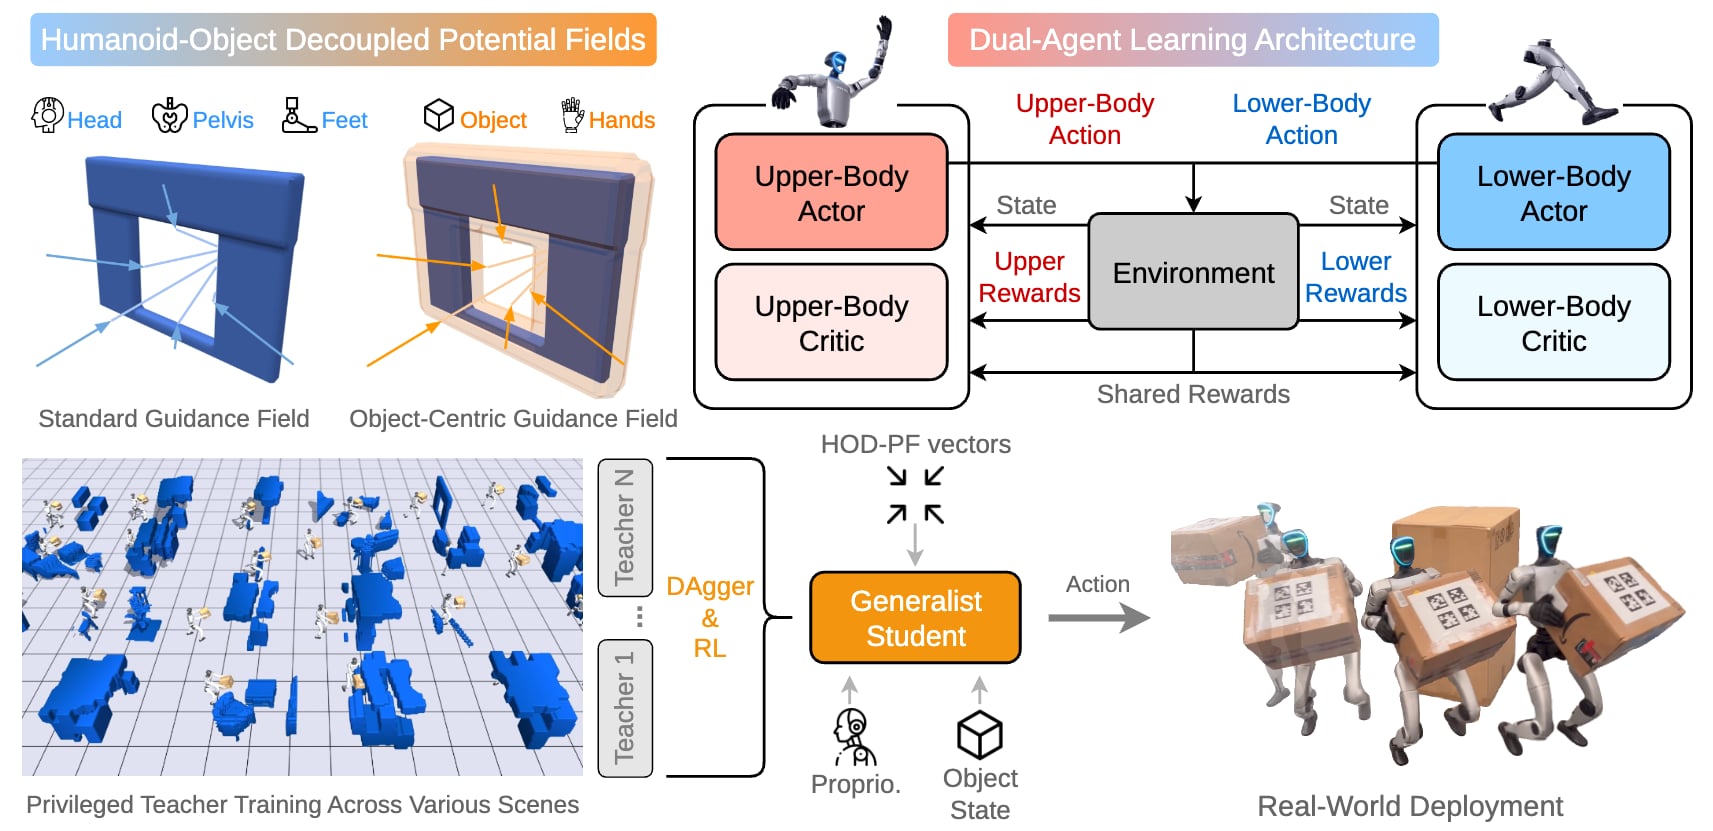
Humanoid-Object Decoupled Potential Fields(top left): a Standard Guidance Field guides the robot's head, pelvis, and feet, while an Object-Centric Guidance Field guides the carried object and the robot's hands.
Dual-Agent Learning Architecture(top right): the whole-body control is split between an upper-body actor-critic and a lower-body actor-critic, each with its own body-specific reward set, but remain coordinated via unified state observations and shared whole-body rewards.
Specialist-to-Generalist Training(bottom): privileged teacher policies are trained across diverse procedurally generated and realistic scenes, then distilled via DAgger and RL fine-tuning into a single generalist student policy that is deployed on the real Unitree G1 humanoid robot.
Simulation Results.
Hotice shows strong effectiveness and generalizability to diverse and challenging obstacle settings in MuJoCo.
Our method effectively handles a wide range of realistic simulated indoor environments.
Hotice is also highly adaptable to other object shapes, like spheres and cylinders.
Real-World Results.
Hotice achieves strong performance in real-world deployment across representative obstacle types (side, overhead, and ground).
With a pickup policy, Hotice enables a complete pipeline for picking up the box from a support surface and transporting it to a human.